What Enterprise Admins Can Actually Control in AI Agent Platforms
Admins should set limits on data, tools, and authority first.
Enterprise AI agent platforms should be judged on what admins can restrict before an agent does anything. The short answer: set boundaries on data, tools, and authority before the agent touches a record, triggers a payment, or routes a decision — not after.
Why you need controls before an AI agent acts, not after
A wrong answer and a wrong action are different problems. An AI agent can modify a database before anyone reviews what it did. One mistake can then ripple through connected systems before anyone notices. Admin responsibility must start before the agent is given any authority to act.
A rule telling a model not to share private data does not stop an over-permissioned retrieval tool from fetching it anyway. Workflows that cross many systems give policy checks more chances to be skipped. Persistent memory — stored context the agent carries between tasks — can lock in bad information. Gravitee's State of AI Agent Security 2026 report found that 88% of organizations said they had confirmed or suspected AI agent security incidents in the last year. You must control the data, tools, and authority available at every step, not just at the end.
Four things admins must set up before an agent is allowed to act
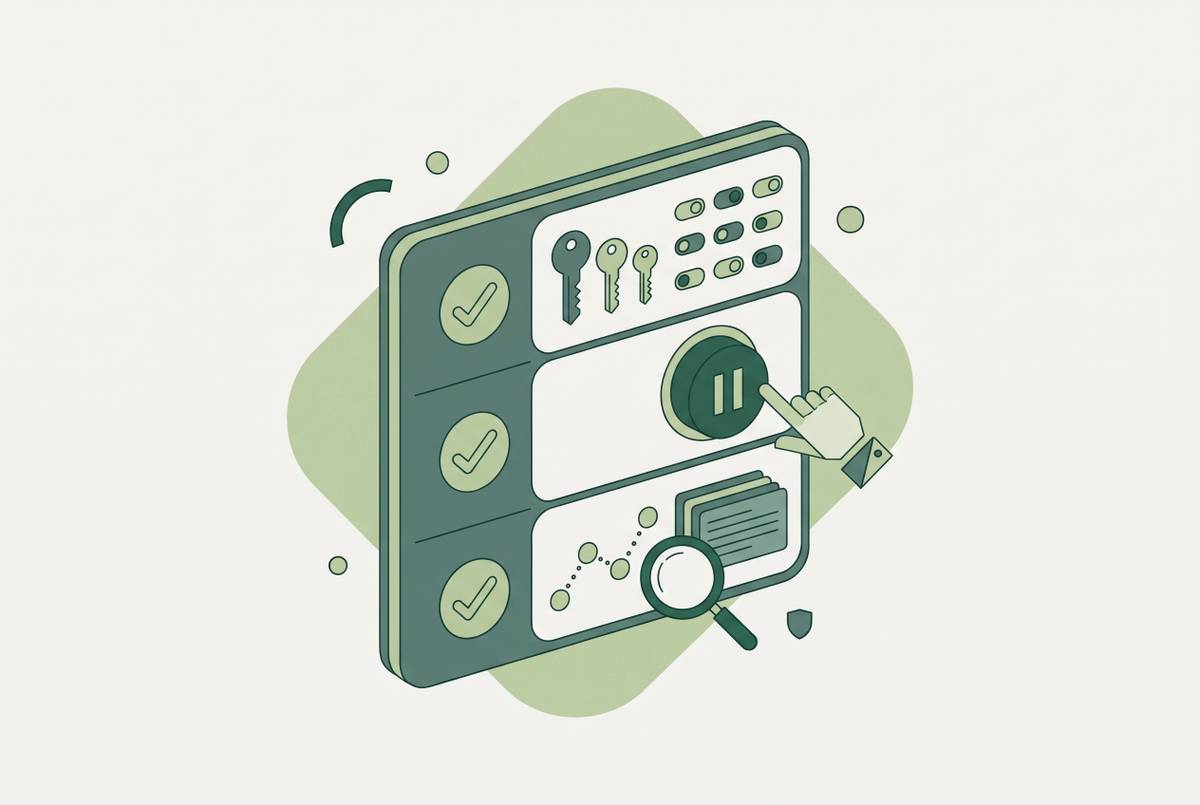
The four areas are: Permission, Approval, Audit Trail, and Kill Switch. Permission defines what the agent can do and how far. Approval sets where a human must decide before the agent moves on. The audit trail keeps the evidence you need to review decisions later. The kill switch defines how an admin safely stops or reverses the agent.
A permission boundary without an escalation path creates a dead end. An approval without a record cannot be defended in a review. Revoking one agent's access is impossible if all agents share the same login. AI-GRACE, by John Cuneo, David Chun, and Gaurav Khanna, published on arXiv in September 2026, builds controls and evidence together from the goals and obligations of each use case. It defines an "Agent Operating Envelope" — the actions the agent may take and the conditions for escalation. Admins must write and version that specification for each named workflow. Each one needs an accountable owner. Start with permissions as the first boundary.
Permissions: where the real boundary lives
Permissions must control both what reaches the agent and what leaves it. When an agent retrieves data through a connected server or search pipeline, its access rights should match the access rules already in place for that data in the original system. A separately maintained permission list can drift out of sync. A prompt saying "do not reveal customer personal data" cannot stop retrieval through an over-permissioned connection. Enforcement must happen at the moment of retrieval.
Admins set up lists of approved and blocked tools — specific APIs, databases, and external services — for each agent. Those rights should not come from the credentials of whoever deployed the agent. A person may approve access within limits they have set, stating the scope and how long it lasts. Read and write permissions must stay separate. Data classification tags (labels that describe how sensitive a piece of data is) determine what may enter the agent's working memory for a given task. Those data bundles must be tested and versioned before being used in production. This makes access a formal deployment setting rather than an instruction the model is simply expected to follow.
Role membership alone is too broad. Enforcement needs user identity, data classification, the application being used, and the sensitivity of the specific action being requested. Uploading public marketing copy and uploading regulated customer records are not the same, even if the same role requests both. The permission layer must tell them apart before any data moves.
Approval gates: deciding which actions still need a human to say yes
Permission to use a tool does not mean every action through that tool is automatically approved. Approval gates set which permitted actions still need a human to judge them. Every new deployment should start with a human approving each consequential action. Moving to a lighter-touch model — where a human monitors but does not pre-approve — should depend on proven quality for that specific action type. For some actions, pre-approval should stay in place permanently.
You make that call by classifying actions by their consequences. Ask: can the action be undone, what is its value, and is it routine or unusual? Thresholds then define when escalation is needed, based on spending limits, confidence scores, and transaction types. The gate needs a clear line: approval design must address the risks of acting in the wrong context and making changes to systems without authorization.
Read-only actions and easily reversible low-value actions can run without gates. Irreversible or high-value actions need them. You must also track how long human reviews take. An unsustainable review load leads to informal bypasses. Measured performance can justify narrowing review requirements, but convenience alone cannot establish that an action is safe.
Exception ownership: the control most governance programs forget to assign
A gate produces work that someone must own. Without a named owner for exceptions, the queue either blocks indefinitely or gets bypassed. That is a governance design failure. The person accountable for what an agent can do must be known before an exception ever arrives. A generic "admin" queue does not provide that accountability.
Each agent needs a business owner who answers for its decisions in an audit, regulatory review, or post-incident analysis. The agent's risk profile must state which actions are permitted, which are prohibited, and when escalation is required. Routing then assigns compliance, budget, and data-access exceptions to their respective owners. The review schedule must also be agreed in advance. Changes in data, regulation, or business context should trigger reassessment.
The practical test is simple. If a post-incident review cannot name the person accountable for authorizing a consequential action's scope, the exception ownership layer was never configured.
Decision records: what the audit trail must capture to be useful
"Order #4782 created" records an event. It leaves out what the agent assessed, which options it considered, what information shaped its choice, and which policy allowed the action. In a supplier decision, useful evidence could include the supplier assessed, the criteria weighted, inventory state, and forecast. The required detail depends on the workflow and its obligations.
The record must capture the original prompt or trigger, tool calls, and data sources accessed. It must also preserve the active identity and permission scope, the version of the governing policy, the result, and whether that policy explicitly allowed the action. The same record must include human approvals, corrections, and exceptions, along with the reasons for those exceptions. Ordinary action logs are not enough. On their own, they cannot show private data revealed through tool calls or systematic bias in how decisions were made.
AI-GRACE treats evidence requirements as conditions that must be met before deployment, based on applicable obligations. Your organization must specify the proof it needs. You must confirm the platform can produce it before going live. The key distinction is between model-level controls and a context layer that tracks data from its source to the agent, with classification tags. That evidence layer must be designed before deployment.
Kill switch and revocation: what "pause or revoke" actually means in a live system
Each agent needs its own login credentials rather than a shared account. That way, one can be stopped without disrupting the others. Access to APIs and other integrations must use tokens (access keys that can be revoked) limited to specific tools and data sources. An admin must be able to revoke a token, disable an integration, or pause a workflow without waiting for a software release.
The containment procedure must be written and tested in advance. It must cover pausing execution, revoking credentials, and preserving the audit trail for incident analysis. Thresholds for unusual behavior must define when a problem escalates to the named exception owner. AI-GRACE derives how and when to interrupt or roll back an agent from the risk assessment of each use case. Those triggers belong in the pre-deployment specification.
Some changes can be undone; others cannot. Irreversible actions require pre-execution approval. This connects the kill switch's limits to both approval design and the question of whether a workflow is ready to run at all.
How easy it is to detect and undo actions should shape deployment decisions
A harmful action becomes harder to correct once other systems have acted on it. A well-known failure pattern is minor errors compounding quietly while systems follow instructions that have drifted from what the organization intended. Monitoring that eventually finds the problem may still leave too much time for the error to spread. A deployment assessment must look at that window before granting the agent authority.
The assessment must establish how an unusual action will surface — through monitoring, escalation, or a failure in a downstream process. It must distinguish actions that can be undone automatically, undone manually, or not undone at all. Blast radius makes the consequences concrete: if the agent is working from wrong information, how many records, systems, or decisions may be affected before the problem is contained? Plausible failures for that specific workflow must then be matched to controls that can detect and contain them.
The cost comparison must cover the cost of acting, the cost of delay, and the cost of failure. A cheap action that goes undetected or cannot be reversed may be very costly to fix. That should inform who has approval authority, how deployment is configured, and what goes into incident reporting. It also shows why a performance baseline must be agreed before production starts.
How should an enterprise measure whether an AI agent is actually working?
User counts, prompt counts, and agent counts show how much a deployment is used. They cannot show whether it succeeds. Your measurement framework must define the authorized business result instead — a resolved case, a completed record, an approved decision. The baseline needs a named owner and an agreed measurement period. Without a record of the prior state, a new failure cannot reliably be distinguished from a pre-existing problem.
Comparing models requires looking at workload quality, speed, risk, and total cost across both AI and human effort. The cost of one approved result includes platform fees, model usage, human review time, and rework. Model spend alone gives an incomplete picture. Measurement must also separate estimated potential value from observed results, and time saved from cash savings. Exception-rate thresholds then establish when performance requires a review of the operating envelope.
A platform that does not lock you into one model — but keeps the context, business rules, and decision history — lets you assess new models and agents against the same workflow record. Corrections and exceptions give you evidence you can keep. You do not need to rebuild the baseline for each replacement. Measurement tells admins when to expand the operating envelope, tighten it, or revoke authority.
What a complete pre-deployment checklist covers in practice
The permission check must confirm that approved and blocked tool lists are version-controlled. Access must be enforced at retrieval time. Every permitted data source must have classification tags. Access rules from the original source system must govern what the agent can reach. Read and write rights must stay separate. Any action that writes or changes state needs explicit authorization.
The approval check needs action categories grouped by their consequences. It needs thresholds that determine whether to proceed or escalate, and tested paths to named owners. It also needs a baseline for review load. The ownership check requires a named business owner, a documented risk profile, and exception routing by failure type. The schedule for reviewing the operating envelope must be agreed and calendared before deployment.
The evidence check requires a decision record format covering triggers, tool calls, identity, permission scope, policy version, results, and human interventions. Required evidence must follow from applicable obligations and be producible by the platform. Retention periods and access controls for records must be documented. The revocation check requires per-agent credentials and independently revocable integration tokens. It also needs a tested containment procedure with a named owner, and thresholds that escalate unusual behavior.
The measurement check requires a workflow outcome metric, a named measurement owner, an agreed period, and a documented pre-production baseline. The cost of one approved result must include platform, model, review, and rework costs, with an exception threshold for reviewing authority. These are deployment preconditions. Operating envelopes must be reviewed when conditions change. The evidence layer makes that review possible.
Sources
- AI-GRACE: A Use-Case Operationalization Framework for Agentic AI: From Organizational Objectives and Obligations to Deployment Capabilities and Architecture
- State of AI Agent Security Report 2026
- AGL-1: The Enterprise AI Governance Layer as a Control Plane for Trusted Enterprise Intelligence
- The Law of Stop: Interruptibility, Injunctions, and the Governance of Agentic AI